Cuda toolkit 3.1 downloads
Содержание:
- A Note on Concurrency
- Windows
- Miscellaneous
- Какую версию CUDA выбрать
- Host Code
- CUDA C++ language and compiler improvements
- MacOS
- Fast GPU, Fast Memory… Right?
- Windows XP, Windows VISTA, Windows 7
- Where To From Here?
- What is Unified Memory?
- What’s New in cuDNN 8.2
- Key Features
- CUDA Performance Profiling
- Linux
- Installing cuDNN On Windows
A Note on Concurrency
Keep in mind that your system has multiple processors running parts of your CUDA application concurrently: one or more CPUs and one or more GPUs. Even in our simple example, there is a CPU thread and one GPU execution context. Therefore, we have to be careful when accessing the managed allocations on either processor, to ensure there are no race conditions.
Simultaneous access to managed memory from the CPU and GPUs of compute capability lower than 6.0 is not possible. This is because pre-Pascal GPUs lack hardware page faulting, so coherence can’t be guaranteed. On these GPUs, an access from the CPU while a kernel is running will cause a segmentation fault.
On Pascal and later GPUs, the CPU and the GPU can simultaneously access managed memory, since they can both handle page faults; however, it is up to the application developer to ensure there are no race conditions caused by simultaneous accesses.
In our simple example, we have a call to after the kernel launch. This ensures that the kernel runs to completion before the CPU tries to read the results from the managed memory pointer. Otherwise, the CPU may read invalid data (on Pascal and later), or get a segmentation fault (on pre-Pascal GPUs).
Windows
When installing CUDA on Windows, you can choose between the Network Installer and the Local Installer. The Network Installer
allows you to download only the files you need. The Local Installer is a stand-alone installer with a large initial download.
For more details, refer to the Windows Installation Guide.
Perform the following steps to install CUDA and verify the installation.
- Launch the downloaded installer package.
- Read and accept the EULA.
- Select «next» to download and install all components.
- Once the download completes, the installation will begin automatically.
- Once the installation completes, click «next» to acknowledge the Nsight Visual Studio Edition installation summary.
- Click «close» to close the installer.
- Navigate to the CUDA Samples’ nbody directory.
- Open the nbody Visual Studio solution file for the version of Visual Studio you have installed.
- Open the «Build» menu within Visual Studio and click «Build Solution».
-
Navigate to the CUDA Samples’ build directory and run the nbody sample.
Note: Run samples by navigating to the executable’s location, otherwise it will fail to locate dependent resources.
Perform the following steps to install CUDA and verify the installation.
- Launch the downloaded installer package.
- Read and accept the EULA.
- Select «next» to install all components.
- Once the installation completes, click «next» to acknowledge the Nsight Visual Studio Edition installation summary.
- Click «close» to close the installer.
- Navigate to the CUDA Samples’ nbody directory.
- Open the nbody Visual Studio solution file for the version of Visual Studio you have installed.
- Open the «Build» menu within Visual Studio and click «Build Solution».
-
Navigate to the CUDA Samples’ build directory and run the nbody sample.
Note: Run samples by navigating to the executable’s location, otherwise it will fail to locate dependent resources.
NVIDIA provides Python Wheels
for installing CUDA through pip,
primarily for using CUDA with Python. These packages are intended for runtime use and do
not currently include developer tools (these can be installed separately).
Please note that with this installation method, CUDA installation environment is managed
via pip and additional care must be taken to set up your host environment to use CUDA
outside the pip environment.
Prerequisites
To install Wheels, you must first install the nvidia-pyindex package,
which is required in order to set up your pip installation to fetch additional Python
modules from the NVIDIA NGC PyPI repo. If your pip and setuptools Python modules are not
up-to-date, then use the following command to upgrade these Python modules. If these
Python modules are out-of-date then the commands which follow later in this section may
fail.
py -m pip install --upgrade setuptools pip wheel
You should
now be able to install the nvidia-pyindex
module.
py -m pip install nvidia-pyindex
If your project is using a
requirements.txt file, then you can add the following line to your
requirements.txt file as an alternative to installing the
nvidia-pyindex
package:
--extra-index-url https://pypi.ngc.nvidia.com
Procedure
Install the CUDA runtime package:
py -m pip install nvidia-cuda-runtime-cu11
Optionally, install additional packages as listed below using the following
command:
py -m pip install nvidia-<library>
Metapackages
The following metapackages will install the latest version of the named component on
Windows for the indicated CUDA version. «cu11» should be read as «cuda11».
- nvidia-cuda-runtime-cu11
- nvidia-cuda-cupti-cu11
- nvidia-cuda-nvcc-cu11
- nvidia-nvml-dev-cu11
- nvidia-cuda-nvrtc-cu11
- nvidia-nvtx-cu11
- nvidia-cuda-sanitizer-api-cu11
- nvidia-cublas-cu11
- nvidia-cufft-cu11
- nvidia-curand-cu11
- nvidia-cusolver-cu11
- nvidia-cusparse-cu11
- nvidia-npp-cu11
- nvidia-nvjpeg-cu11
These metapackages install the following packages:
- nvidia-nvml-dev-cu114
- nvidia-cuda-nvcc-cu114
- nvidia-cuda-runtime-cu114
- nvidia-cuda-cupti-cu114
- nvidia-cublas-cu114
- nvidia-cuda-sanitizer-api-cu114
- nvidia-nvtx-cu114
- nvidia-cuda-nvrtc-cu114
- nvidia-npp-cu114
- nvidia-cusparse-cu114
- nvidia-cusolver-cu114
- nvidia-curand-cu114
- nvidia-cufft-cu114
- nvidia-nvjpeg-cu114
Miscellaneous
- CUDA Samples
- This document contains a complete listing of the code samples that are
included with the NVIDIA CUDA Toolkit. It describes each code sample,
lists the minimum GPU specification, and provides links to the source
code and white papers if available. - CUDA Demo Suite
- This document describes the demo applications shipped with the CUDA Demo Suite.
- CUDA on WSL
- This guide is intended to help users
get started with using NVIDIA CUDA on Windows Subsystem for Linux (WSL 2).
The guide covers installation and running CUDA applications and containers
in this environment. - Multi-Instance GPU (MIG)
- This edition of the user guide describes the Multi-Instance GPU feature of the NVIDIA A100 GPU.
- CUDA Compatibility
- This document describes CUDA Compatibility, including CUDA Enhanced Compatibility and CUDA Forward Compatible Upgrade.
- CUPTI
- The CUPTI-API. The CUDA Profiling Tools Interface (CUPTI)
enables the creation of profiling and tracing tools that target CUDA applications. - Debugger API
- The CUDA debugger API.
- GPUDirect RDMA
- A technology introduced in Kepler-class GPUs and CUDA 5.0,
enabling a direct path for communication between the GPU and a third-party peer
device on the PCI Express bus when the devices share the same upstream
root complex using standard features of PCI Express. This document
introduces the technology and describes the steps necessary to enable a
GPUDirect RDMA connection to NVIDIA GPUs within the Linux device
driver model. - GPUDirect Storage
- The documentation for GPUDirect Storage.
- vGPU
- vGPUs that support CUDA.
Какую версию CUDA выбрать
На данный момент самая свежая версия NVIDIA CUDA Ubuntu — девятая. Если вы собрались создавать собственное программное обеспечение на основе этой платформы, лучше всего начать с этой или восьмой версии. Но если вам нужно запустить в системе программу, которая уже собрана под определенный вариант CUDA, то вам придется ставить именно его. Потому что между более старыми и новыми вариациями есть серьезные отличия, и приложение может попросту не заработать. Попытайтесь запустить нужную вам программу и посмотрите, каких библиотек ей не хватает в сообщении об ошибке:

Или же эту информацию можно найти в описании программы. Обычно разработчики пишут, какая версия CUDA нужна для работы. А теперь давайте рассмотрим, как выполняется установка CUDA на Ubuntu 16.04, 17.10 и другие модификации этого дистрибутива.
Host Code
The main function declares two pairs of arrays.
  float *x, *y, *d_x, *d_y;
  x = (float*)malloc(N*sizeof(float));
  y = (float*)malloc(N*sizeof(float));

  cudaMalloc(&d_x, N*sizeof(float));
  cudaMalloc(&d_y, N*sizeof(float));
The pointers and point to the host arrays, allocated with in the typical fashion, and the and arrays point to device arrays allocated with the function from the CUDA runtime API. The host and device in CUDA have separate memory spaces, both of which can be managed from host code (CUDA C kernels can also allocate device memory on devices that support it).
The host code then initializes the host arrays. Here we set to an array of ones, and to an array of twos.
  for (int i = 0; i < N; i++) {
    x = 1.0f;
    y = 2.0f;
  }
To initialize the device arrays, we simply copy the data from and to the corresponding device arrays and using , which works just like the standard C function, except that it takes a fourth argument which specifies the direction of the copy. In this case we use to specify that the first (destination) argument is a device pointer and the second (source) argument is a host pointer.
  cudaMemcpy(d_x, x, N*sizeof(float), cudaMemcpyHostToDevice);
  cudaMemcpy(d_y, y, N*sizeof(float), cudaMemcpyHostToDevice);
After running the kernel, to get the results back to the host, we copy from the device array pointed to by to the host array pointed to by by using with .
cudaMemcpy(y, d_y, N*sizeof(float), cudaMemcpyDeviceToHost);
Launching a Kernel
The kernel is launched by the statement:
saxpy<<<(N+255)/256, 256>>>(N, 2.0, d_x, d_y);
The information between the triple chevrons is the execution configuration, which dictates how many device threads execute the kernel in parallel. In CUDA there is a hierarchy of threads in software which mimics how thread processors are grouped on the GPU. In the CUDA programming model we speak of launching a kernel with a grid of thread blocks. The first argument in the execution configuration specifies the number of thread blocks in the grid, and the second specifies the number of threads in a thread block.
Thread blocks and grids can be made one-, two- or three-dimensional by passing dim3 (a simple struct defined by CUDA with , , and members) values for these arguments, but for this simple example we only need one dimension so we pass integers instead. In this case we launch the kernel with thread blocks containing 256 threads, and use integer arithmetic to determine the number of thread blocks required to process all elements of the arrays ().
For cases where the number of elements in the arrays is not evenly divisible by the thread block size, the kernel code must check for out-of-bounds memory accesses.
Cleaning Up
After we are finished, we should free any allocated memory. For device memory allocated with , simply call . For host memory, use as usual.
cudaFree(d_x);
  cudaFree(d_y);
  free(x);
  free(y);
CUDA C++ language and compiler improvements
CUDA 11 is also the first release to officially include CUB as part of the CUDA Toolkit. CUB is now one of the supported CUDA C++ core libraries.
One of the major features in nvcc for CUDA 11 is the support for link time optimization (LTO) for improving the performance of separate compilation. LTO, using the or options, stores intermediate code during compilation and then performs higher-level optimizations at link time, such as inlining code across files.
nvcc in CUDA 11 adds support for ISO C++17 and support for new host compilers across PGI, gcc, clang, Arm, and Microsoft Visual Studio. If you want to experiment with host compilers not yet supported, nvcc supports a new flag during the compile-build workflow. nvcc adds other new features, including the following:
- Improved lambda support
- Dependency file generation enhancements (, options)
- Pass-through options to the host compiler
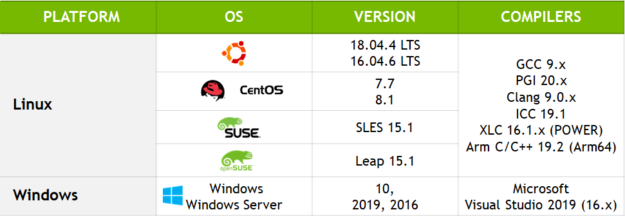 Figure 4. Platform support in CUDA 11.
MacOS
| Description of Download | Link to Binaries | Documents |
| Developer Drivers for MacOS | download | Getting Started Guide Mac Release Notes *Updated*CUDA C Programming Guide CUDA C Best Practices Guide CUDA Reference Manual API Reference PTX ISA 2.1 Visual Profiler User Guide Visual Profiler Release Notes Fermi Compatibility Guide *Updated*Fermi Tuning Guide CUBLAS User Guide CUFFT User Guide CUDA Developer Guide for Optimus Platforms License |
|
CUDA Toolkit
|
download | |
| GPU Computing SDK code samples | download | CUDA C/C++ Release NotesCUDA Occupancy Calculator License |
Fast GPU, Fast Memory… Right?
Right! But let’s see. First, I’ll reprint the results of running on two NVIDIA Kepler GPUs (one in my laptop and one in a server).
| Laptop (GeForce GT 750M) | Server (Tesla K80) | |||
|---|---|---|---|---|
| Version | Time | Bandwidth | Time | Bandwidth |
| 1 CUDA Thread | 411ms | 30.6 MB/s | 463ms | 27.2 MB/s |
| 1 CUDA Block | 3.2ms | 3.9 GB/s | 2.7ms | 4.7 GB/s |
| Many CUDA Blocks | 0.68ms | 18.5 GB/s | 0.094ms | 134 GB/s |
Now let’s try running on a really fast Tesla P100 accelerator, based on the Pascal GP100 GPU.
> nvprof ./add_grid
...
Time(%)      Time     Calls       Avg       Min       Max  Name
100.00%  2.1192ms         1  2.1192ms  2.1192ms  2.1192ms  add(int, float*, float*)
Hmmmm, that’s under 6 GB/s: slower than running on my laptop’s Kepler-based GeForce GPU. Don’t be discouraged, though; we can fix this. To understand how, I’ll have to tell you a bit more about Unified Memory.
For reference in what follows, here’s the complete code to add_grid.cu from last time.
#include <iostream>
#include <math.h>

// CUDA kernel to add elements of two arrays
__global__
void add(int n, float *x, float *y)
{
  int index = blockIdx.x * blockDim.x + threadIdx.x;
  int stride = blockDim.x * gridDim.x;
  for (int i = index; i < n; i += stride)
    y = x + y;
}

int main(void)
{
  int N = 1<<20;
  float *x, *y;

  // Allocate Unified Memory -- accessible from CPU or GPU
  cudaMallocManaged(&x, N*sizeof(float));
  cudaMallocManaged(&y, N*sizeof(float));

  // initialize x and y arrays on the host
  for (int i = 0; i < N; i++) {
    x = 1.0f;
    y = 2.0f;
  }

  // Launch kernel on 1M elements on the GPU
  int blockSize = 256;
  int numBlocks = (N + blockSize - 1) / blockSize;
  add<<<numBlocks, blockSize>>>(N, x, y);

  // Wait for GPU to finish before accessing on host
  cudaDeviceSynchronize();

  // Check for errors (all values should be 3.0f)
  float maxError = 0.0f;
  for (int i = 0; i < N; i++)
    maxError = fmax(maxError, fabs(y-3.0f));
  std::cout << "Max error: " << maxError << std::endl;

  // Free memory
  cudaFree(x);
  cudaFree(y);

  return 0;
}
The code that allocates and initializes the memory is on lines 19-27.
Windows XP, Windows VISTA, Windows 7
| Description of Download | Link to Binaries | Documents |
| Developer Drivers for WinXP (197.13) | 32-bit64-bit | |
| Developer Drivers for WinVista & Win7 (197.13) | 32-bit64-bit | |
| Notebook Developer Drivers for WinXP | 32-bit64-bit | |
| Notebook Developer Drivers for WinVista & Win7 | 32-bit64-bit | |
|
CUDA Toolkit
|
32-bit64-bit | Getting Started Guide for WindowsRelease Notes CUDA C Programming Guide CUDA C Best Best Practices Guide OpenCL Programming Guide OpenCL Best Best Practices Guide OpenCL Implementation Notes CUDA Reference Manual API Reference PTX ISA 2.0 Visual Profiler User Guide Visual Profiler Release Notes Fermi Compatibility Guide Fermi Tuning Guide CUBLAS User GuideCUFFT User Guide License |
| NVIDIA Performance Primitives (NPP) library | 32-bit64-bit | |
| GPU Computing SDK code samples | 32-bit64-bit | Release Notes for CUDA C Release Notes for DirectCompute Release Notes for OpenCL CUDA Occupancy Calculator License |
| NVIDIA OpenCL Extensions | Compiler_Options D3D9 Sharing D3D10 Sharing D3D11 Sharing Device Attribute Query Pragma Unroll |
Where To From Here?
I hope that this post has whet your appetite for CUDA and that you are interested in learning more and applying CUDA C++ in your own computations. If you have questions or comments, don’t hesitate to reach out using the comments section below.
I plan to follow up this post with further CUDA programming material, but to keep you busy for now, there is a whole series of older introductory posts that you can continue with (and that I plan on updating / replacing in the future as needed):
- How to Implement Performance Metrics in CUDA C++
- How to Query Device Properties and Handle Errors in CUDA C++
- How to Optimize Data Transfers in CUDA C++
- How to Overlap Data Transfers in CUDA C++
- How to Access Global Memory Efficiently in CUDA C++
- Using Shared Memory in CUDA C++
- An Efficient Matrix Transpose in CUDA C++
- Finite Difference Methods in CUDA C++, Part 1
- Finite Difference Methods in CUDA C++, Part 2
- Accelerated Ray Tracing in One Weekend with CUDA
There is also a series of CUDA Fortran posts mirroring the above, starting with An Easy Introduction to CUDA Fortran.
You might also be interested in signing up for the online course on CUDA programming from Udacity and NVIDIA.
There is a wealth of other content on CUDA C++ and other GPU computing topics here on the NVIDIA Parallel Forall developer blog, so look around!
What is Unified Memory?
Unified Memory is a single memory address space accessible from any processor in a system (see Figure 1). This hardware/software technology allows applications to allocate data that can be read or written from code running on either CPUs or GPUs. Allocating Unified Memory is as simple as replacing calls to or with calls to , an allocation function that returns a pointer accessible from any processor ( in the following).
cudaError_t cudaMallocManaged(void** ptr, size_t size);
When code running on a CPU or GPU accesses data allocated this way (often called CUDA managed data), the CUDA system software and/or the hardware takes care of migrating memory pages to the memory of the accessing processor. The important point here is that the Pascal GPU architecture is the first with hardware support for virtual memory page faulting and migration, via its Page Migration Engine. Older GPUs based on the Kepler and Maxwell architectures also support a more limited form of Unified Memory.
What’s New in cuDNN 8.2
cuDNN 8.2 is optimized for A100 GPUs delivering up to 5x higher performance versus V100 GPUs out of the box and includes new optimizations and APIs for applications such as conversational AI and computer vision. It has been redesigned for ease of use, application integration, and offers greater flexibility to developers.
cuDNN 8.2 highlights include:
- Support for BFloat16 for CNNs on NVIDIA Ampere architecture GPUs
- Flexibly fuse operators such as convolutions, point-wise operations and reductions at runtime to speed up CNNs
- Faster out-of-the-box performance with new dynamic kernel selection infrastructure
- Up to 2X higher RNN performance with new optimizations and heuristics
cuDNN 8.2 is now available as six smaller libraries, providing granularity when integrating into applications. Developers can download cuDNN or pull it from framework containers on NGC.
Read the latest cuDNN release notes for a detailed list of new features and enhancements.
Key Features
- Tensor Core acceleration for all popular convolutions including 2D, 3D, Grouped, Depth-wise separable, and Dilated with NHWC and NCHW inputs and outputs
- Optimized kernels for computer vision and speech models including ResNet, ResNext, EfficientNet, EfficientDet, SSD, MaskRCNN, Unet, VNet, BERT, GPT-2, Tacotron2 and WaveGlow
- Supports FP32, FP16, BF16 and TF32 floating point formats and INT8, and UINT8 integer formats
- Arbitrary dimension ordering, striding, and sub-regions for 4d tensors means easy integration into any neural net implementation
- Speed up fused operations on any CNN architecture
cuDNN is supported on Windows and Linux with Ampere, Turing, Volta, Pascal, Maxwell, and Kepler GPU architectures in data center and mobile GPUs.
CUDA Performance Profiling
When developing GPU code or using GPU packages in R, you may encounter functional and performance problems. To solve these problems efficiently, you can use CUDA developer tools such as cuda-gdb, Nsight and the NVIDIA Visual Profiler or . For this example, I will show you how to profile our cuFFT example above using , the command line profiler included with the CUDA Toolkit (check out the post about how to use to profile any CUDA program). My testing environment is R 3.0.2 on a 12-core Intel Xeon CPU (E5645 @ 2.40GHz and 24G RAM) combined with an NVIDIA Tesla GPU (K20Xm with 6GB device memory).
There are two approaches to launching with R.
- Use as a wrapper to launch R by typing nvprof R, then run the GPU solver and exit, or use to launch R with a batch script:
- Launch in a separated console. R executes the GPU solver and exits as normal, and in another console captures the GPU behavior and prints the profile.
Here is the nvprof output for our FFT wrapper function, for a signal of 2^26 elements:
==18067== Profiling application: /home/patricz/tools/R/lib64/R/bin/exec/R
==18067== Profiling result:
 Time(%) Time Calls Avg Min Max Name
  55.41% 277.50ms 1 277.50ms 277.50ms 277.50ms
  39.30% 196.82ms 1 196.82ms 196.82ms 196.82ms
  1.35% 6.7531ms 1 6.7531ms 6.7531ms 6.7531ms void spRadix0128B::kernel1Mem(Complex*, Complex const *, unsigned int, unsigned int, unsigned int, divisor_t, Complex const *, Complex const *, coordDivisors_t, Coord, Coord, unsigned int, unsigned int, float, int, int)
  1.34% 6.7084ms 1 6.7084ms 6.7084ms 6.7084ms void spRadix0032B::kernel1Mem(Complex*, Complex const *, unsigned int, unsigned int, unsigned int, divisor_t, Complex const *, Complex const *, coordDivisors_t, Coord, Coord, unsigned int, unsigned int, float, int, int)
  1.30% 6.5350ms 1 6.5350ms 6.5350ms 6.5350ms void spRadix0128C::kernel1Mem(Complex*, Complex const *, unsigned int, unsigned int, unsigned int, divisor_t, Complex const *, Complex const *, coordDivisors_t, Coord, Coord, unsigned int, unsigned int, float, int, int)
  1.30% 6.4979ms 1 6.4979ms 6.4979ms 6.4979ms void spRadix0128B::kernel3Mem(Complex*, Complex const *, unsigned int, unsigned int, divisor_t, coordDivisors_t, Coord, unsigned int)
==14905== API calls:
Time(%) Time Calls Avg Min Max Name
 52.35% 502.32ms 2 251.16ms 223.84ms 278.49ms cudaMemcpy
 24.08% 231.04ms 3 77.012ms 491.74us 229.92ms cudaFree
 23.02% 220.89ms 2 110.44ms 580.53us 220.30ms cudaMalloc
 0.41% 3.9122ms 664 5.8910us 278ns 232.60us cuDeviceGetAttribute
 0.07% 625.78us 8 78.222us 67.720us 97.719us cuDeviceTotalMem
 0.05% 483.86us 8 60.482us 50.428us 106.37us cuDeviceGetName
 0.01% 81.052us 4 20.263us 13.612us 36.908us cudaLaunch
 0.01% 79.330us 1 79.330us 79.330us 79.330us cudaGetDeviceProperties
 0.00% 24.473us 56 437ns 300ns 1.0670us cudaSetupArgument
 0.00% 20.558us 7 2.9360us 538ns 9.2310us cudaGetDevice
 0.00% 14.040us 4 3.5100us 2.0570us 7.1580us cudaFuncSetCacheConfig
 0.00% 7.4470us 1 7.4470us 7.4470us 7.4470us cudaDeviceSynchronize
 0.00% 4.9390us 12 411ns 283ns 597ns cuDeviceGet
 0.00% 3.7660us 3 1.2550us 417ns 2.5800us cuDeviceGetCount
 0.00% 3.2650us 4 816ns 568ns 1.4930us cudaConfigureCall
 0.00% 2.6450us 4 661ns 314ns 1.3870us cudaPeekAtLastError
 0.00% 1.9140us 4 478ns 402ns 548ns cudaGetLastError
 0.00% 1.1380us 1 1.1380us 1.1380us 1.1380us cuDriverGetVersion
 0.00% 1.1310us 1 1.1310us 1.1310us 1.1310us cuInit
Linux
| Description of Download | Link to Binaries | Documents |
| Developer Drivers for Linux (260.19.26) | 32-bit64-bit | README_Linux.txt |
|
CUDA Toolkit
|
Linux Getting Started Guide Release Notes Release Notes Errata CUDA C Programming Guide CUDA C Best Practices Guide OpenCL Programming Guide OpenCL Best Practices Guide OpenCL Implementation Notes CUDA Reference Manual (pdf) CUDA Reference Manual (chm) API Reference PTX ISA 2.2 CUDA-GDB User Manual Visual Profiler User Guide Visual Profiler Release Notes Fermi Compatibility Guide Fermi Tuning Guide CUBLAS User Guide CUFFT User Guide CUSPARSE User Guide CURAND User Guide CUDA Developer Guide for Optimus Platforms License | |
| CUDA Toolkit for Fedora 13 | 32-bit64-bit | |
| CUDA Toolkit for RedHat Enterprise Linux 5.5 | 32-bit64-bit | |
| CUDA Toolkit for Ubuntu Linux 10.04 | 32-bit64-bit | |
| CUDA Toolkit for RedHat Enterprise Linux 4.8 | 32-bit64-bit | |
| CUDA Toolkit for OpenSUSE 11.2 | 32-bit64-bit | |
| CUDA Toolkit for SUSE Linux Enterprise Desktop 11 SP1 | 32-bit64-bit | |
| NVIDIA Performance Primitives (NPP) library | 32-bit64-bit | NPP Release Notes NPP License |
| GPU Computing SDK code samples | download | CUDA C/C++ Release Notes CUDA Occupancy Calculator License |
| NVIDIA OpenCL Extensions | Compiler_Options D3D9 Sharing D3D10 Sharing D3D11 Sharing Device Attribute Query Pragma Unroll |
Installing cuDNN On Windows
For the latest compatibility software versions of the OS, CUDA, the CUDA driver, and the NVIDIA hardware, see the cuDNN Support
Matrix.
Install up-to-date NVIDIA graphics drivers on your Windows system.
Procedure
- Go to: NVIDIA download drivers
- Select the GPU and OS version from the drop-down menus.
- Download and install the NVIDIA driver as indicated on that web page. For more
information, select the ADDITIONAL INFORMATION tab for
step-by-step instructions for installing a driver. - Restart your system to ensure the graphics driver takes effect.
Refer to the following instructions for installing CUDA on Windows,
including the CUDA driver and toolkit: NVIDIA CUDA Installation Guide for Windows.
Procedure
- Go to: NVIDIA cuDNN home page.
- Click Download.
- Complete the short survey and click Submit.
- Accept the Terms and Conditions. A list of available download versions of cuDNN displays.
- Select the cuDNN version to want to install. A list of available
resources displays. - Extract the cuDNN archive to a directory of your choice.
The following steps describe how to build a cuDNN dependent
program.
About this task
Before issuing the following commands, you’ll need to replace x.x
and 8.x.x.x with your specific CUDA and cuDNN versions and package date.
Where:
- The CUDA directory path is referred to as C:\Program Files\NVIDIA
GPU Computing Toolkit\CUDA\vx.x - The cuDNN directory path is referred to as
<installpath>
Procedure
- Navigate to your <installpath> directory containing cuDNN.
-
Unzip the cuDNN package.
cudnn-x.x-windows-x64-v8.x.x.x.zip
or
cudnn-x.x-windows10-x64-v8.x.x.x.zip
-
Copy the following files into the CUDA Toolkit directory.
- Copy <installpath>\cuda\bin\cudnn*.dll
to C:\Program Files\NVIDIA GPU Computing
Toolkit\CUDA\vx.x\bin. - Copy <installpath>\cuda\include\cudnn*.h to
C:\Program Files\NVIDIA GPU Computing
Toolkit\CUDA\vx.x\include. - Copy <installpath>\cuda\lib\x64\cudnn*.lib to
C:\Program Files\NVIDIA GPU Computing
Toolkit\CUDA\vx.x\lib\x64.
- Copy <installpath>\cuda\bin\cudnn*.dll
-
Set the following environment variables to point to where cuDNN
is located. To access the value of the $(CUDA_PATH) environment
variable, perform the following steps:- Open a command prompt from the Start menu.
- Type Run and hit Enter.
- Issue the control sysdm.cpl command.
- Select the Advanced tab at the top of the
window. - Click Environment Variables at the bottom of the
window. -
Ensure the following values are set:
Variable Name: CUDA_PATH
Variable Value: C:\Program Files\NVIDIA GPU Computing Toolkit\CUDA\vx.x
-
Include cudnn.lib in your Visual Studio project.
- Open the Visual Studio project and right-click on the project
name. - Click Linker > Input > Additional
Dependencies. - Add cudnn.lib and click
OK.
- Open the Visual Studio project and right-click on the project
Navigate to your <installpath> directory containing cuDNN and delete the old cuDNNlib and header files. Reinstall the latest cuDNN version by following the steps in .